Automated resource optimization for all your Kubernetes workloads
From mission critical applications to AI inference, Kubex does it for you
- Eliminate manual tuning
- Drastically reduce cost and waste
- Deterministic and policy controlled
- Agents added to your team
- Start in a read-only mode
- Review optimization proposals
- Action or automate on your terms, safely
Trusted by Platform owners at leading enterprises

Real results in leading enterprises
-
Global pharmaceutical leader
907 cores. 8.8 TB. $585K a year, reclaimed in two weeks.
Connected one cluster, let Kubex automate the rightsizing, and had the easiest savings story they’d ever taken to leadership.
-
Global media and entertainment leader
6,000 cores gone. $1.2M back.
“We knew we were overprovisioning. We didn’t know where. Kubex showed us cluster by cluster and fixed it.” Sr. Director, Cloud Architecture
-
Global enterprise software leader
$140K a year, from a single Kubernetes cluster.
The savings from their first cluster, before rolling Kubex out across the estate.
What is holding you back when managing your infrastructure?
Pick a problem to see how Kubex handles it.
-
Your engineers spend too much time tuning resources
Kubex keeps containers, nodes and autoscaling tuned continuously, and your team works with it from the tools and AI agents they already use.
-
OOM kills and throttling keep paging your team
Kubex tunes requests and limits together from observed peaks, so workloads get what they need before they fail.
-
You pay for capacity your workloads never use
Kubex sizes every container from long-term workload models and packs nodes so empty ones can go.
-
Your autoscaling and rightsizing work against each other
Kubex tunes HPA targets and replica bounds together with rightsizing, so vertical and horizontal scaling work as one.
-
Your GPUs run well below capacity
Kubex lets several models share one GPU, each with a sized slice of compute and memory.
-
Inference costs more than it should
Kubex tunes vLLM settings and KV cache to real traffic in a closed loop, getting more throughput from the same hardware.
-
Automated changes feel too risky to trust
Every change comes forward as a proposal, checked against your guardrails. Review and approve them for automation.
One engine.
Autonomous optimization.
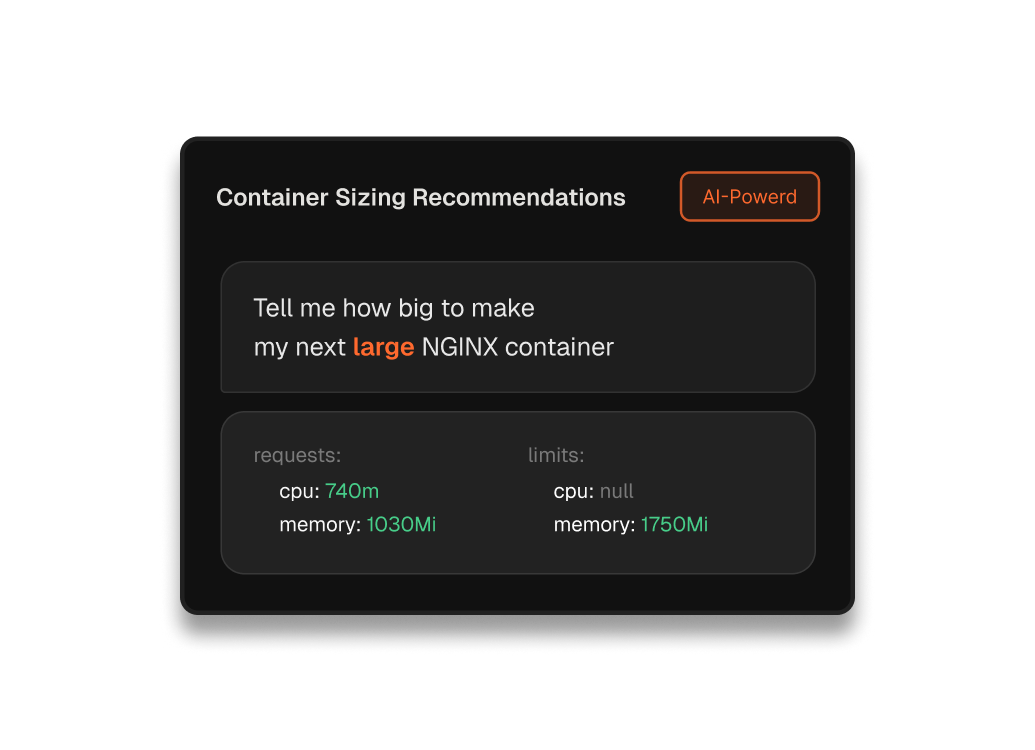
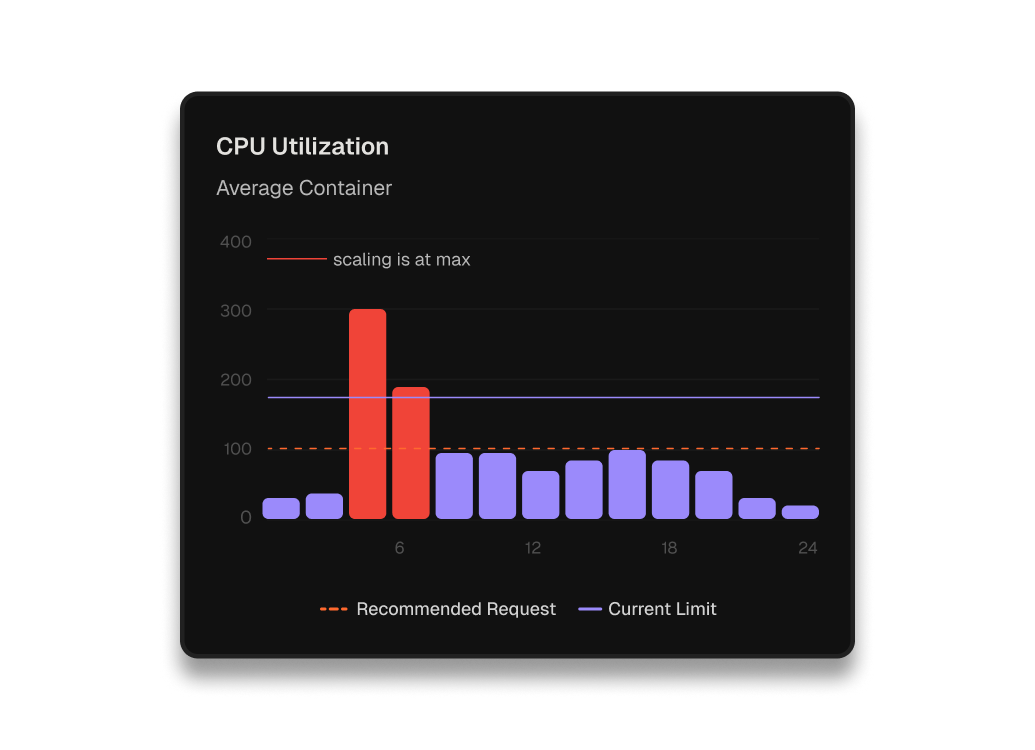
Container rightsizing
CPU and memory requests and limits set from real usage, for every container.
- Requests and limits tuned together
- Undersized workloads raised before anything is trimmed
- New containers start at the right size
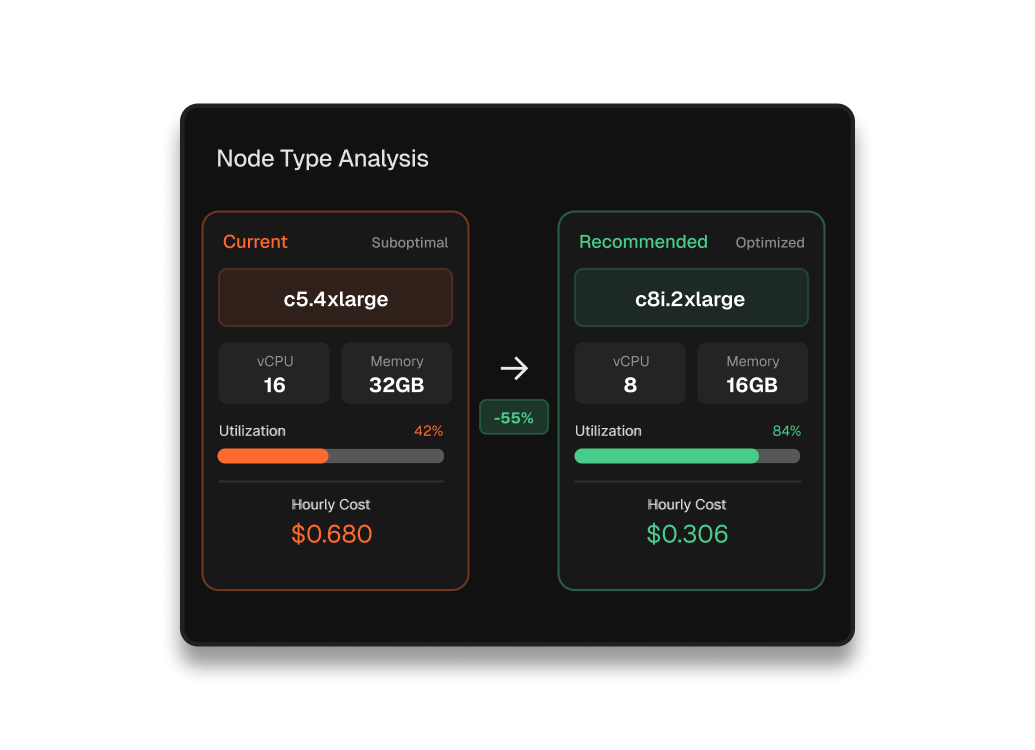
Node optimization
The right node types and counts for the workloads you actually run.
- Works with Karpenter, picking the instance types it provisions
- Managed node groups and Cluster Autoscaler too
- Freed capacity turns into fewer nodes
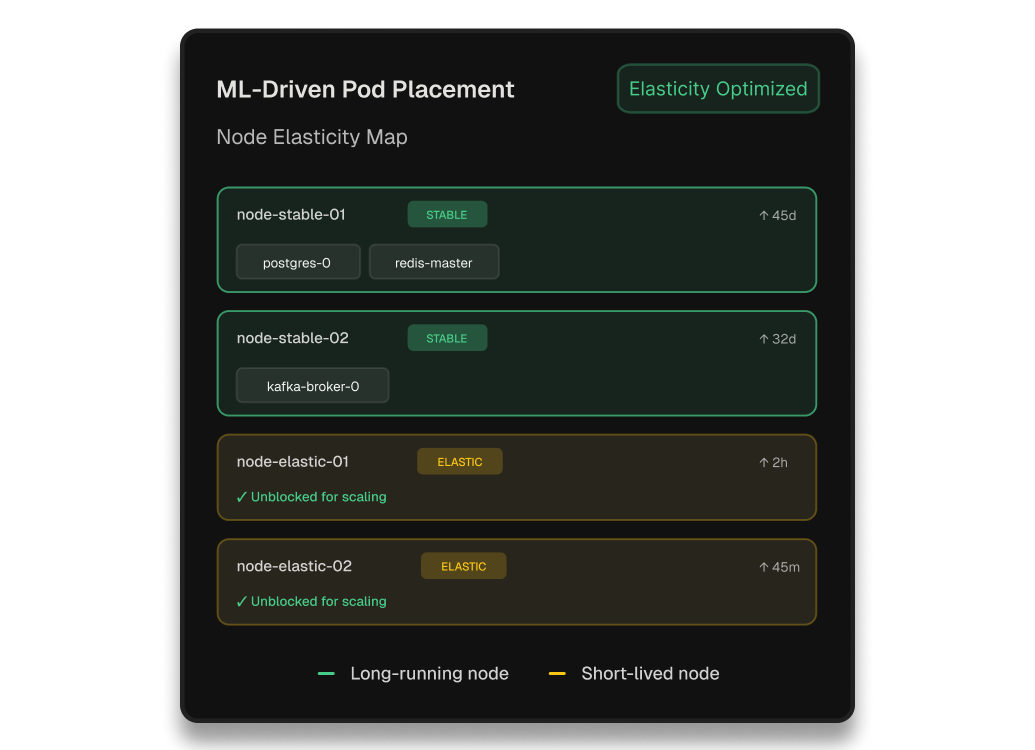
Bin packing
Long-running pods placed so nodes fill evenly and empty ones can go.
- Consolidates without breaking disruption budgets
- Respects affinity, taints and topology rules
- Runs on a schedule you set
HPA tuning
Target utilization and replica bounds tuned with rightsizing, so the two work together.
- Avoids saturation and idle replicas
- Container specs and HPA settings recommended together
JVM tuning
Java heap sized together with container memory.
- Stops JVM workloads over-requesting memory
- Without risking OOM kills
GPU fractioning
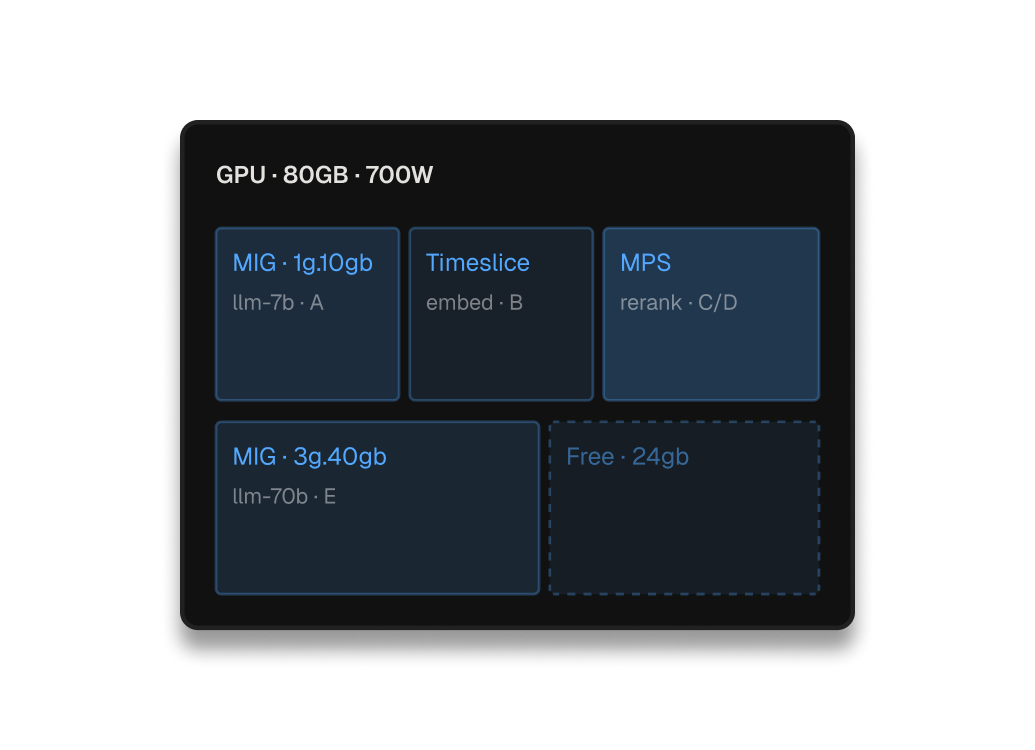
Several models share one GPU, each with a sized slice of compute and memory.
- Time-slicing, MIG or MPS, chosen per workload
- GPU memory limits enforced per container
- Slices resized as demand changes
KV cache tuning
KV cache sized to real traffic, automatically, so reserved GPU memory gets used.
- Tracks cache usage and preemptions
- Frees memory vLLM reserved but never used
- Keeps headroom for traffic spikes
Continuous vLLM optimization
KV cache sized to real traffic, automatically, so reserved GPU memory gets used.
- Tracks cache usage and preemptions
- Frees memory vLLM reserved but never used
- Keeps headroom for traffic spikes
Kubex Automation Engine
- Zero-downtime resizing
- Guardrails on every change
- New pods start right-sized
- GitOps ready
Agentic harness
The market leading agentic & deterministic engine accessed from where you work.
Works within your AI tools of choice to 4x your productivity
-
Agent
One Kubex Agent. Ask it, approve its changes, or let it act on its own.
-
Skills
What the agent knows how to do. Use them in Claude, Cursor or your own tools.
-
Tasks
Scheduled prompts that put skills to work. Turn on the examples, or write your own.
-
Proposals
Every change the agent, skills and tasks find comes forward as a proposal. Review and approve them for automation.
Optimize Resources and Elasticity with Agentic AI
A single optimization engine spanning consumers, intelligence, and infrastructure, from containers to nodes to cloud instances.

Platform Teams & Engineers
Monitor, control, and optimize infrastructure without manual tuning.

AI Agents & LLM Systems
Programmatically interact with Kubex to manage workloads dynamically.

Agentic Harness

Deterministic ML Engine
Predicts workload behavior with precision and consistency.
Automation Engine
Policy compliant optimizations without manual intervention
Infra Matching Engine
Aligns workloads with the most efficient compute resources.

Containerized services scaled and bin-packed in real time.
Databases and stateful sets matched to durable, right-sized resources.
AI right-sized and dynamically matched to GPU resources.

Kubex augments scheduling decisions with predictive placement.
Provisions and drains nodes ahead of demand, not after.
Horizontal & event-driven pod scaling tuned by the ML engine.
GPU-aware scheduling for high-utilization AI workloads.
Just-in-time node provisioning optimized for cost and fit.
Runs natively across OpenShift and vanilla Kubernetes.

General-purpose compute matched to workload profiles.
Accelerators sliced via MIG, time-slicing, and MPS so every GPU runs at full utilization.
Throughput and capacity balanced against workload needs.

AWS, Azure, and GCP capacity selected by price and availability.
Specialized GPU clouds tapped for burst AI capacity.
Owned datacenter hardware optimized alongside the cloud.
Proven Results at Scale
See the measurable impact organizations achieve with our platform.
Rapid Cost Reduction
Toil Reduction
Reduction in OOM Kills
The Inference Throughput
What our Customers Say
From fast-growing startups to enterprise platforms.